Article / Public
Muse Spark Open: Meta's open-weight model introduced with BF16 and NVFP4 checkpoints
Hugging Face introduced Meta's Muse Spark Open, a model with approximately 816 billion parameters. The coding-focused model accepts multimodal inputs, with memory capacity a central deployment concern.
Hugging Face introduced Meta's open-weight Muse Spark Open model in an October 15, 2026 post and reported that BF16 and NVFP4 checkpoints were available. According to the post, the model has approximately 816 billion total parameters, 42 billion active parameters per token and a context window of up to one million tokens. Meta positions it particularly for coding and long developer workflows.
What is available?
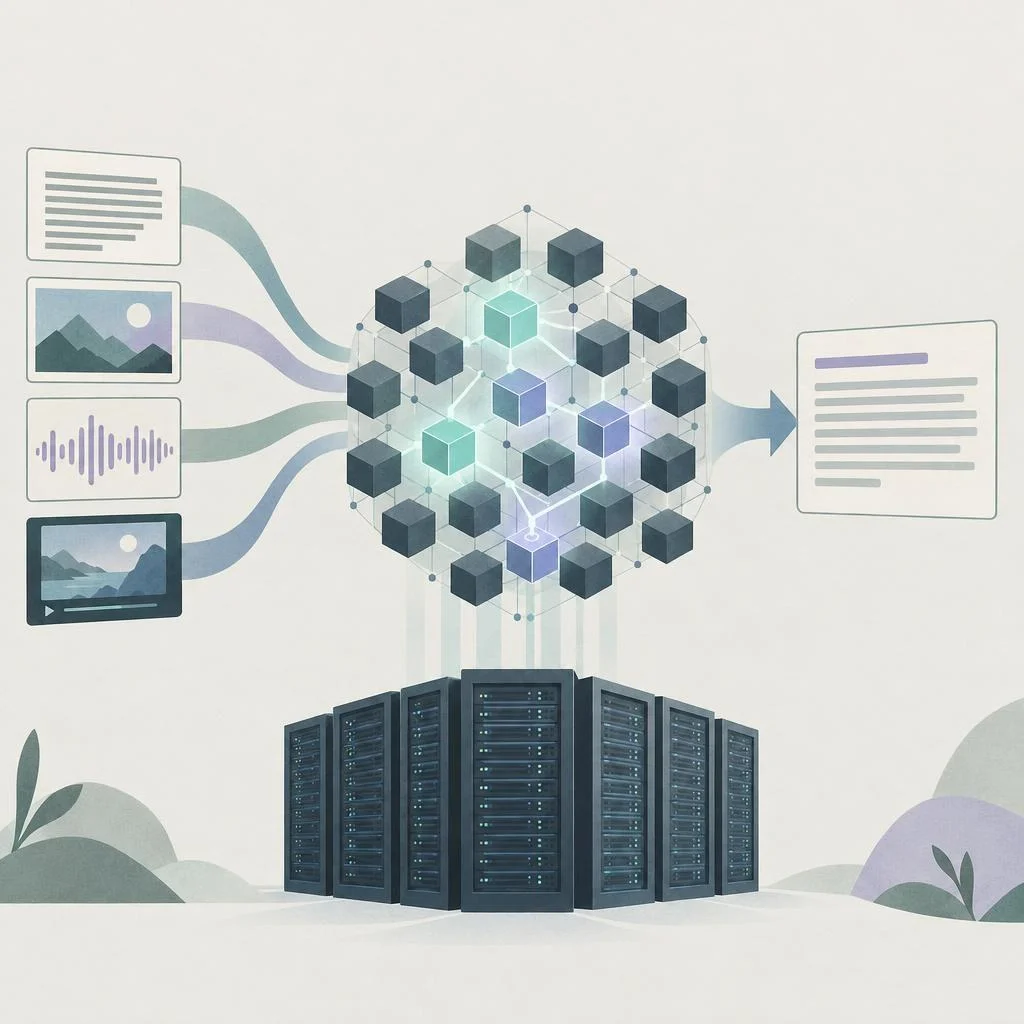
According to the specifications Hugging Face reports, Muse Spark Open accepts text, image, audio and video inputs and produces text responses. That distinction matters: Multimodal support here means that different types of content can be supplied as inputs. The post does not say the model generates images, audio or video. Developers can ask questions about different input types through the same model.
Coding features prominently in Meta's description. The company says it trained the model on real developer workflows, including multi-file refactors and long debugging sessions. The source also lists reading a codebase, writing code, debugging and calling tools. These are the producer's statements about the model's purpose and training; they do not, by themselves, constitute comparative results demonstrating code quality.
From different inputs to a text response
- Inputs
Text, images, audio and video are supplied to the model.
- Shared context
Tokens from different input types share the same context window.
- Text output
The model produces text responses about different content.
The difference between 816 billion and 42 billion
The model uses a mixture-of-experts, or MoE, architecture. According to Hugging Face's technical explanation, each MoE layer contains 256 experts, and a router selects eight of them for each token. This separates the model's total parameter count from the number of parameters used when processing a particular token.
Approximately 42 billion active parameters means the entire model does not participate in computation in the same way at every step. The approximately 816 billion total describes all of the model's weights. These figures answer different questions: The first describes the scale of active computation per token, while the second describes the model's total size. Deployment planning requires keeping them distinct.
The context window of up to one million tokens is not reserved for text alone. According to the post, image, video and audio tokens share that window with text. This capacity therefore needs to be understood as space used jointly by all input types. Visual or audio content added to a long coding conversation also becomes part of that shared context.
Expert selection and weights retained in memory
- Router
Selects eight of 256 experts per token in each MoE layer.
- Active parameters
Approximately 42 billion parameters participate in computation per token.
- Total weights
All experts of the approximately 816-billion-parameter model remain in memory.
The test reported by Hugging Face
Separately from the producer's statements, the Hugging Face authors report testing quantized versions on a Mac M3 Ultra with 512 GB of memory. The post says an imatrix-calibrated 2-bit version generated 18 tokens per second. This is an operational observation reported by the Hugging Face team, not a test conducted by Urazo.
That test concerns a version at a different precision from the announcement's BF16 and NVFP4 checkpoints. The checkpoint formats and the configuration behind the speed result therefore need to remain separate. Including the hardware and quantization details alongside the 18-tokens-per-second figure preserves the conditions under which it was reported.
Limitations and scope of the evidence
According to the post, all 256 experts remain in memory. Selecting only eight per token does not remove the full model's memory requirement; deployment still needs capacity to hold the weights of an 816-billion-parameter model. The reported speed also applies to the specified Mac and 2-bit version. The supplied evidence does not support extending it to other hardware, checkpoints or context lengths. Nor does the information provide comparative measurements of coding success or response quality across a one-million-token context.
Urazo interpretation
The practical significance is the combination of open weights, different input types and a coding-focused design in one model. For teams evaluating it, the key distinction is that accessible weights and easy deployment are not the same thing. The active parameter count explains the computation structure, while keeping every expert in memory shapes infrastructure decisions. An initial evaluation makes more sense when it considers the model's fit for the intended workflow, the selected version and available memory capacity together.
Sources
Image: AI-generated illustration. Explanatory animations are conceptual diagrams, not measurements or product demos.